


Regression testing and failure analysis for learned robot policies.
Gauntlet answers one question for VLA, diffusion, and scripted policies:
How does this policy fail, and has the new checkpoint regressed against the last one?
It wraps any policy behind a small adapter, runs it across a seeded grid of simulator perturbations (lighting, camera pose, clutter, object pose, actuation latency, sensor corruption, instruction paraphrase), and writes a report that breaks failures down by condition instead of averaging them away.
58-second overview (real rollouts, report and CLI output):
gauntlet-overview.mp4
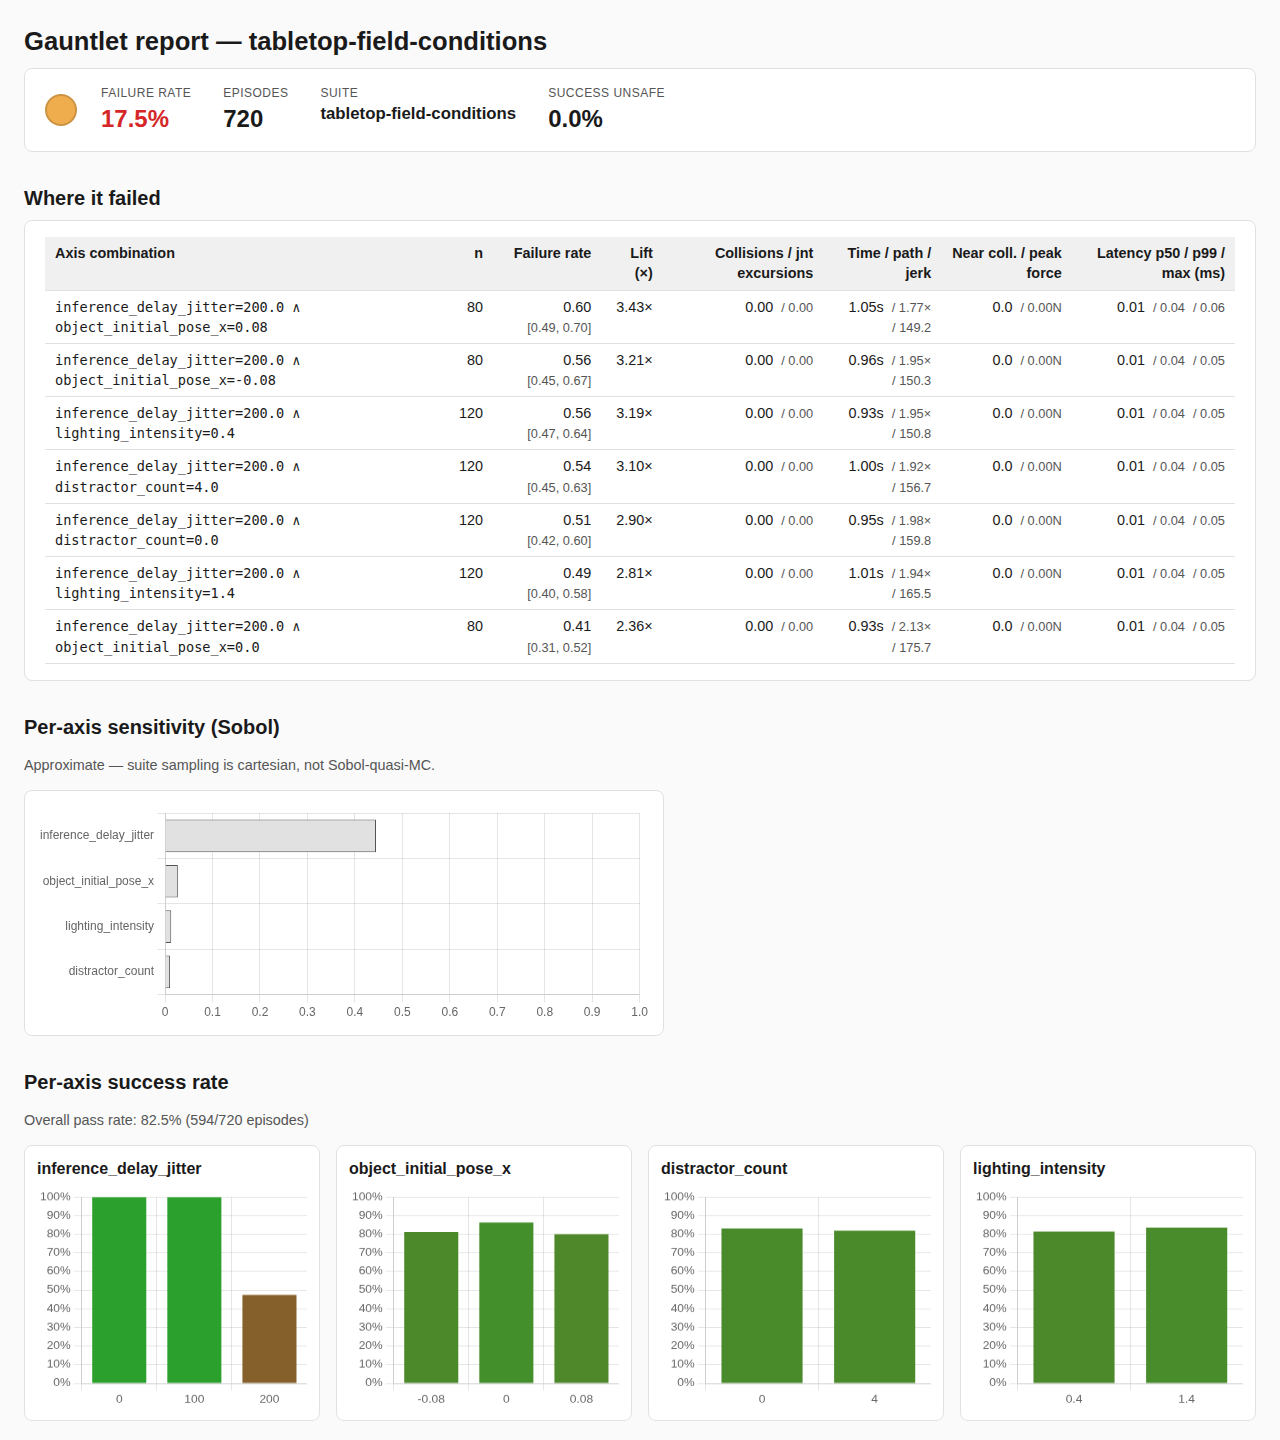
Report from the field-conditions example: the baseline is perfect up to 100 ms of control latency and falls to 47% at 200 ms. Every failure cluster is a latency cluster.
A success rate is a mean, and a mean hides the thing you care about. Two checkpoints at 80% can fail in completely different places, and a fine-tune that gains two points on the clean scene can lose its entire safety margin on one axis. Gauntlet makes the per-condition picture the default output:
- Failure clusters first. Axis combinations whose failure rate is well above baseline, with Wilson CIs, ranked by lift.
- Paired comparisons.
gauntlet compare/gauntlet diffline two runs up cell by cell (common random numbers + McNemar when seeds match) and flag regressions, not just a headline delta. - Sensitivity indices. Per-axis first- and total-order Sobol indices, corrected for rollout seed noise.
- Reproducible. Every episode is determined by
(suite, cell, seed);gauntlet replayre-simulates any one bit-for-bit, optionally with one axis nudged.
Every GitHub Release
ships reference-benchmark.zip: two policies (a closed-loop controller
and a degraded copy of it) on the smoke suite and the
field-conditions suite, with the
compare / diff deltas. Unzip and open any report.html.
docs/crop-row.md
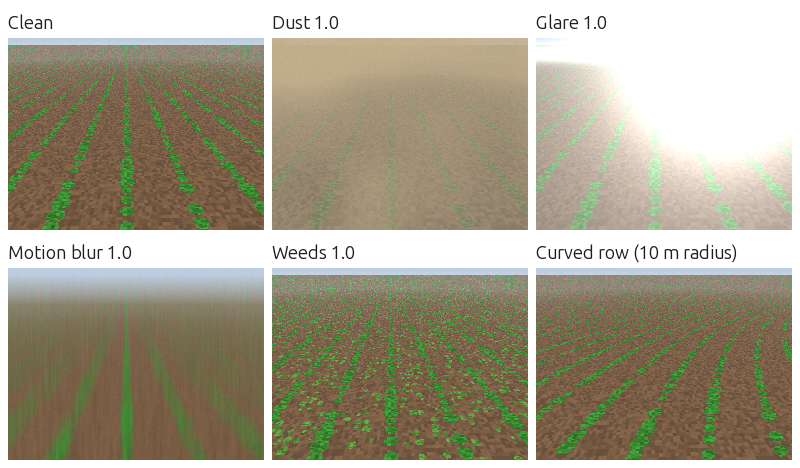
evaluates two row-guidance perception models, a classical
excess-green detector and a small CNN trained on clean images, on 480
rollouts each under dust, glare, motion blur, weeds and curved rows
(procedurally generated scenes). Overall success differs by under
3 points; the per-condition report shows the CNN fails every curved
row while the classical detector collapses in dense dust (3%) and weeds.
pip install gauntlet-robotics            # core: MuJoCo, torch-free
pip install 'gauntlet-robotics[hf]'      # + OpenVLA / HuggingFace adapter
pip install 'gauntlet-robotics[lerobot]' # + SmolVLA / pi0 / diffusion adapters
Other extras: pybullet, genesis, isaac (backends), monitor
(drift detection), video, ros2. Python ≥ 3.11.
git clone https://github.com/mhussainahmad/gauntlet && cd gauntlet
uv sync

# 1. One policy, one suite: 24 rollouts, a few seconds.
uv run gauntlet run examples/suites/tabletop-smoke.yaml --policy random --out out/smoke
xdg-open out/smoke/report.html        # macOS: open

# 2. Baseline vs. regressed checkpoint on field-style conditions: 2 x 720 rollouts, ~15 s.
uv run python scripts/generate_reference_benchmark.py \
  --suite examples/suites/tabletop-field-conditions.yaml --out out/field
cat out/field/diff.txt
Each run writes episodes.json (one record per rollout), report.json
(the analysis) and a self-contained report.html.
A policy is anything with act(obs) -> action:
# my_policy.py
import numpy as np

class MyPolicy:
    def __init__(self) -> None:
        self.model = load_my_checkpoint()          # your code

    def act(self, obs: dict[str, np.ndarray]) -> np.ndarray:
        # obs: ee_pos, cube_pos, target_pos, ... (+ "image" with render_in_obs=True)
        return self.model(obs["ee_pos"], obs["cube_pos"])  # 7-D EE twist + gripper

def make_policy() -> MyPolicy:
    return MyPolicy()
uv run gauntlet run examples/suites/tabletop-basic-v1.yaml \
--policy my_policy:make_policy --out out/mine
uv run gauntlet compare out/last_week/episodes.json out/mine/episodes.jsonThird-party packages can also register policies and envs through entry
points; see docs/plugin-development.md.
| Tasks | Tabletop pick-and-place (tabletop), planar pushing (tabletop-push: no grasp, success only once the cube settles in the target), three-cube stacking with per-subtask credit (tabletop-stack), a mobile-base variant (tabletop-mobile), and camera-guided crop-row following (crop-row: perception under dust, glare, blur, weeds and curved rows). |
| Backends | MuJoCo (core; every task), PyBullet (pick-and-place, state and images) and Genesis (pick-and-place; state tested in CI, image rendering not exercised in CI). Isaac Sim adapter written against the Isaac Sim 5.0 API, CI-tested against a mocked runtime but not yet run on hardware. Same action/observation spaces; compare refuses cross-backend diffs unless asked. |
| Perturbation axes | Lighting, camera offset and full extrinsics, object texture / pose / class swap, distractors, OOD initial state, actuation latency, image corruption, colour shift, instruction paraphrase; for crop rows, dust, glare, motion blur, weeds and row curvature. All of them run straight from a suite YAML. |
| Sampling | Cartesian grids, Latin hypercube, Sobol, worst-case search; gauntlet suite plan sizes episodes-per-cell for a target effect. |
| Policy adapters | Random, scripted pick-and-place and push controllers, a classical crop-row detector, OpenVLA (HF), SmolVLA / pi0 / diffusion (LeRobot), GR00T, RDT, Decision Transformer. |
| Analysis | Failure clusters, Wilson CIs, paired compare, per-cell diff, Sobol indices, behavioural metrics (time, path length, jerk), safety counters, gauntlet bisect across checkpoints. Non-finite observations or actions end the episode as a flagged failure instead of silently corrupting it. |
| Operations | Rollout caching, MP4 recording, runtime drift detection, ROS 2 publish/record, fleet aggregation, static dashboard, real-to-sim scene ingestion with a nearest-frame renderer and a smoke-test gaussian-splat fit (gsplat CUDA or pure PyTorch). |
Details for each are in the user guide. Design
decisions are recorded as RFCs and design notes under docs/.
0.5.x is on PyPI as gauntlet-robotics. The public API, on-disk
schemas and CLI flags follow Semantic Versioning;
the contract is in docs/stability.md. Pin
gauntlet-robotics>=0.5,<0.6.
uv sync
uv run ruff check . && uv run ruff format --check .
uv run mypy                 # --strict
uv run pytest               # ~1,800 torch-free tests; extras run in their own CI jobs
See CONTRIBUTING.md and the
property-test notes.
src/gauntlet/
  policy/      # Policy adapter protocol + reference wrappers (Random, Scripted, HF, LeRobot)
  env/         # Parameterized envs — MuJoCo (core) + PyBullet/Genesis/Isaac (extras)
  suite/       # YAML-defined perturbation grid suites (cartesian / LHS / Sobol)
  runner/      # Parallel rollout orchestration + seed management + cache
  report/      # Per-run failure analysis + HTML/JSON generation
  monitor/     # Runtime drift detection + action-entropy ([monitor] extra)
  replay/      # Single-episode replay with axis overrides
  ros2/        # ROS 2 publisher + recorder ([ros2] extra; rclpy via apt/Docker)
  diff/        # Structured per-axis report deltas powering `gauntlet diff`
  aggregate/   # Fleet-wide failure-mode clustering across many runs
  dashboard/   # Self-contained static SPA indexing every report.json
  realsim/     # Real-to-sim scene ingestion + renderers (nearest-frame, gaussian splat)
  plugins.py   # Entry-point discovery for third-party policies / envs
  cli.py       # gauntlet run / report / compare / diff / aggregate /
               # dashboard / realsim / monitor / replay / ros2
MIT, see LICENSE.